
Performance Systems
Awaken keeps big scenes fast with a stack of complementary systems - spatial culling, cached shadows, static batching, distance culling, optional GPU-driven culling, texture compression, MSAA, and render scale - most of them controlled from Render Settings.
The cull → draw path
Every frame the renderer turns the whole scene into a small set of draw calls. The persistent scene cache holds one GPU instance record per object; culling picks which are visible, splits them into instanced groups and merged static chunks, and packs a visible→slot buffer the vertex shader indexes.
Octree frustum culling - always on
Drawables are indexed in a bounded octree (packages/render/src/octree.ts) built once per cache rebuild from world bounding spheres. Each frame the octree is queried against the camera frustum (and any dirty shadow cascades and the preview camera) in one traversal: a node fully inside the frustum contributes its whole subtree with no per-item test, a node fully outside is skipped entirely, and only straddling nodes test their own items. This keeps culling sublinear as object counts grow.
This is not optional and needs no setting - it is how the renderer decides what to draw at all. If only transforms moved (nothing added/removed), the octree is cheaply refit instead of the cache being fully rebuilt.
Cached static shadows - opt-in, on by default
Re-drawing every shadow caster into every cascade each frame is usually the dominant cost. Awaken caches the static-caster depth per cascade and re-bakes only when a cascade is dirty (sun moved, geometry changed, or the texel-snapped region shifted). Covered in full on Shadows. Setting: Cached shadows (default on).
Static batching (index-merge) - opt-in, on by default
Static scenery whose mesh is used by few objects is merged per spatial cell + texture into single draw calls. Geometry stays local; each merged vertex carries an objIndex into a stable per-object transform buffer, so moving an object is a one-slot write, not a re-merge (only adding, removing, or crossing a cell boundary rebuilds a chunk). Opaque and transparent objects never share a chunk, which preserves alpha draw order. Heavily-repeated meshes stay on the instanced path (instancing already collapses them). This is the biggest draw-call win on scenes assembled from many distinct props. Full detail on Static Batching.
Settings (Render Settings → Performance): Static batching (on), Batch threshold (merge a mesh used by ≤ N static objects, 1–32, default 8), and Merge budget (millions of merged vertices before falling back to per-object draws, 4–32, default 8M).
Size-aware distance culling - opt-in, off by default
An object's on-screen size is roughly radius / distance, so Awaken can cull an object once it is too small to matter: it drops any object whose distance from the eye exceeds radius × drawDistanceScale (packages/render/src/distanceCull.ts). Because the threshold scales with each object's own bounding-sphere radius, big things stay visible far away while small clutter culls close - automatically, with no per-object tuning.
It is pure float math with no GPU features, so it runs on the weakest phone (mobile just uses a smaller scale). It runs before packing and applies to the main camera pass only; shadows keep their own shadowDistance. It removes the cost of distant clutter rather than swapping in cheaper geometry, so it is what stands in for content that has no authored LOD levels.
Setting: Draw distance - 0 to 1000 in steps of 25; 0 = off (keep everything, the default), lower = more aggressive; 300–500 is a starting point for weaker devices. It does not apply to opaque per-object draws while GPU cull (exp.) is on.
NOTE
At aggressive scales, a modular building assembled from many small parts can pop apart as its parts cross the threshold at slightly different distances. That is inherent to per-object culling of small parts; HLOD would be the proper fix.
LOD groups - per object, authored or imported
A LodGroup component swaps an object's mesh for a cheaper one as the camera pulls away. meshes is a comma-separated list of mesh asset ids, highest detail first; distances is the ascending list of distances past which each next level takes over, so it has one fewer entry than meshes.
The object keeps one MeshRenderer throughout - only the mesh id changes - so materials, colliders and everything else stay put. A switch only fires once the camera has moved a further 10% past a boundary, so an object sitting exactly on one does not flicker between two meshes.
This is how a source engine's LOD group imports. Such a group lists one mesh per level and shows exactly one at a time, so importing every level as visible geometry stacked two or three near-identical meshes in the same place: z-fighting, doubled darkening, and two to three times the triangles. The import now keeps the highest-detail level on the renderer and hands the rest to this component.
Awaken does not generate levels: there is no runtime decimation and no HLOD. See Limitations.
Depth pre-pass - opt-in, off by default
An opaque depth pre-pass runs before shading, so early-Z rejects occluded fragments and the lit shader runs roughly once per visible pixel. That is a win on dense, high-overdraw scenes and a small net cost on trivial ones, which is why it is off by default. Setting: Depth prepass.
Clustered lighting (Forward+) - opt-in, off by default
Binning lights into a screen-tile x depth-slice grid on the GPU removes the fixed per-fragment light budget: each fragment shades only the lights in its own cluster, up to 32. Without it the shader loops the most important 16 lights. Setting: Clustered Lighting; see PBR & Lighting.
GPU-driven culling - opt-in, capability-gated
This is an advanced path. When enabled and the device supports the indirect-first-instance feature, a compute kernel (CULL_WGSL) frustum-culls every object for the opaque main pass and writes compacted drawIndexedIndirect args, so the CPU does zero per-object culling for that pass. Shadows, the transparent pass, and picking stay on the verified CPU path (transparent stays CPU because indirect instance order is non-deterministic, which would flash order-dependent alpha blending).
It is off by default; the CPU path is the fallback and is what ships. Note that some developer GPUs (and browsers) don't expose indirect-first-instance at all - on those, the flag is a silent no-op and the scene renders through the CPU path unchanged. Setting: GPU cull (exp.).
BC texture compression - opt-in, on by default, capability-gated
When the device supports texture-compression-bc, textures are block-compressed at upload per role (packages/render/src/bc.ts), cutting VRAM 4–8×:
| Role | Format | Ratio | Use |
|---|---|---|---|
| Albedo (opaque) | BC1 | 8× | Colour, no alpha |
| Albedo (alpha) | BC3 | 4× | Colour + alpha |
| Mask (1 channel) | BC4 | 8× | Single-channel masks (roughness/metallic/AO/height) |
| Normal (2 channels) | BC5 | 4× | Tangent-space normals (X,Y; Z reconstructed in-shader) |
Encoding uses bounding-box endpoints - a solid first-pass quality; edge blocks replicate the last texel, so non-multiple-of-4 dimensions are fine. Textures fall back to uncompressed RGBA8 when the feature is absent, so nothing breaks - you just pay full VRAM. Compression is chosen at load per-device rather than baked at import, which keeps the shipped file device-agnostic. The stats overlay reports real post-compression VRAM.
MSAA - anti-aliasing vs. fill cost
With MSAA on, the main scene pass renders into a 4-sample colour target and resolves into the scene texture. Anti-aliasing offers MSAA 4× or Off, and is Off by default: 4× costs GPU fill and bandwidth for little visible gain on textured or foliage-dense scenes, so turn it on per project when geometry edges matter. Only 4× and Off are offered because WebGPU guarantees just those two sample counts; 2× renders black on GPUs without it. Changing it rebuilds the MSAA-dependent pipelines, a brief hitch. MSAA smooths geometry edges only, not texture or shader aliasing.
Render scale - internal resolution
Render scale (0.25–1) multiplies the internal render resolution; the browser upscales the result to the canvas. Below 1 it is a large GPU-fill win for a softer image - the go-to knob for hitting frame rate on low-end GPUs or high-DPI displays. It is applied in the GPU context resize (backing size = client px × device pixel ratio × render scale).
Quality levels - per device, chosen by the game
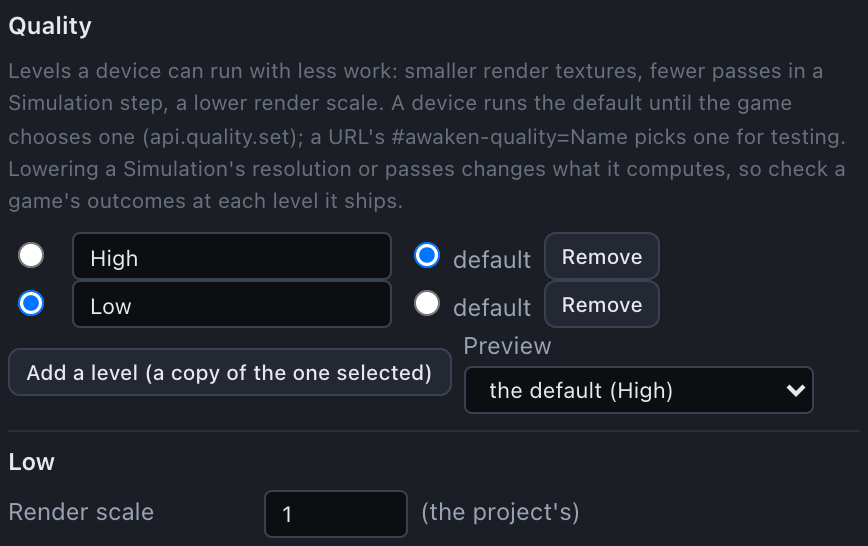
Project Settings > Quality holds named levels: sets of cheaper settings a device can run, so a phone that cannot keep up runs the same project with less work (packages/render/src/quality.ts). Each level changes, over the project's own values:
| Setting | Range | What it does |
|---|---|---|
| Render scale | 0.25–1 | The canvas resolution, in place of Render Settings' Render Scale. |
| A render texture's size | 0.05–1 | A fraction of that texture's own width and height, per render texture. A Simulation over smaller textures does less work a step; an instanced draw that reads one instance per texel draws fewer. |
| A Simulation step's passes | 1–256 | How many times an update step runs each fixed step, per Simulation step (pressure iterations, say). |
A project with no levels, or a level that changes nothing, runs exactly as authored. Mark one level default: a device runs it until the game picks another.
Which level runs, first match wins (chosenQualityLevel):
- the URL's
#awaken-quality=Name(orquality=, in the fragment or the query), for testing on a device; - the level the game chose with
api.quality.set, which is saved and kept for the next launch; - the project's default, else the first level.
Scripts read and choose levels through api.quality:
| Member | Meaning |
|---|---|
api.quality.level | The level this device runs ("" when the project has none) |
api.quality.levels | Every level's name, in the project's order |
api.quality.set(name) | Run that level from now on, and on the next launch. Returns false, and changes nothing, for an unknown name. Switching resets the game's Simulations. |
The Preview select at the top of the Quality settings runs a level in the editor's Scene and Game views. Nothing picks a level from the device on its own: there is no GPU or device-tier detection, so a game that wants one per device offers a setting, or picks from what it measures, and calls api.quality.set.
A level that lowers a Simulation's resolution or passes changes what the Simulation computes, not only how it looks. A game whose outcomes come from a Simulation should check them at every level it ships.
Frames that change nothing - the shipped player rests
A shipped game draws a frame only when something on screen would change: a moved or recoloured object, an upload, a light, a camera or canvas change, a material that reads the clock, or a request. After 30 frames in a row with nothing drawn, no UI moving or animating and nothing held down, the player stops asking for animation frames and runs on a 100 ms timer tick, so scripts, timers and an on-screen clock keep running. Any input, any draw request and any tick that draws or moves the UI bring it back to every display frame at once (apps/player/src/framePacer.ts).
What it means for a script:
- Everything you change through the
api(a move, a mesh, a texture, a light, a global, the camera,api.ui) is seen by itself. - A component field written directly through
api.worldis not: callapi.requestDraw()after it, or it shows on the next frame that draws for another reason (up to 100 ms later when idle). The editor always draws, so this only shows in an export. api.timeScalesets how fast game time runs:1normal,0stopped, in between for slow motion, up to100. Fixed steps,onUpdate'sdt,api.time, timers, physics, animation, particles and the materials' clock follow it; input, UI clicks and UI animations do not, so a pause card still works. With game time at0and nothing else changing, the game draws no new frames, which is what saves a phone's battery under a pause card. It lasts across scene loads: set it back to1when play resumes.
#awaken-always-draw in the URL turns the skipping and the idle tick off. #awaken-perf (or #perf, or App Settings' developer readout) shows a readout with frames drawn and skipped a second, the loop's mode, main-thread and GPU time, fixed steps and the canvas size.
Choosing settings
| Situation | Reach for |
|---|---|
| Many distinct static props, high draw calls | Static Batching (raise Merge Max Uses / Budget) |
| Open world, distant clutter | Draw Distance Scale > 0 |
| Fill-bound on a weak GPU / 4K | Render Scale < 1, MSAA off |
| Lots of shadow draw calls | Keep Shadow Cache on; lower Shadow Distance or Cascade Count |
| Huge object counts, capable GPU | Try GPU Culling |
| Texture VRAM pressure | Keep BC compression on |
| Heavy overdraw (dense foliage, interiors) | Depth Prepass |
| More than 16 visible lights | Clustered Lighting |
| Imported content with authored LOD levels | Nothing - the LodGroup component switches them |
| One project for desktops and phones | Quality levels: a lower Render scale and smaller Simulation textures on the phone level |
| A paused game draining a phone's battery | api.timeScale = 0 under the pause card |
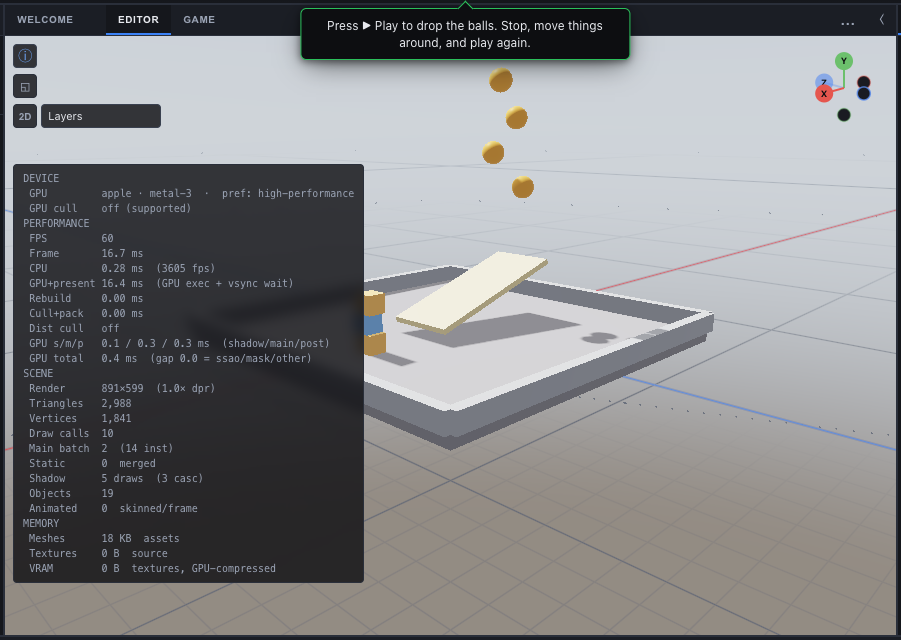
Read the per-pass GPU ms and draw-call counts in the stats overlay first - optimize the pass that is actually slow.
See also
- Static Batching - the index-merge in depth
- Shadows - cached static shadows and cascade cost
- Render Settings - every control on this page
- Mesh Format - the instance buffer and welding that culling and batching consume
- Limitations & Roadmap - occlusion culling and LOD gaps
- Export for Mobile - where quality levels and the resting player matter most